TashkiFlow
OCR / NLP / Android
A scanned page. Arabic text you can use.
A hybrid Arabic OCR pipeline with diacritization, Latin transliteration, and an Android scanning experience.
Thesis Researcher & Developer
Undergraduate thesis research · 2026
The problem &
my contribution
Reading an Arabic document involves more than detecting characters. This project connects recognition, restored diacritics, and readable output in one scanning workflow.
Thesis research, OCR pipeline development, evaluation, and the Android scanning flow.
- Python
- PaddleOCR
- Kraken
- Diacritization
- FastAPI
- Android
Let two OCR engines contribute
PaddleOCR and Kraken feed a hybrid arbitration stage, rather than treating one engine as equally reliable for every image.
Measure each stage separately
Character, word, and diacritic error rates expose different failure modes. The portfolio reports them separately instead of combining them into one accuracy claim.
Give the pipeline an application flow
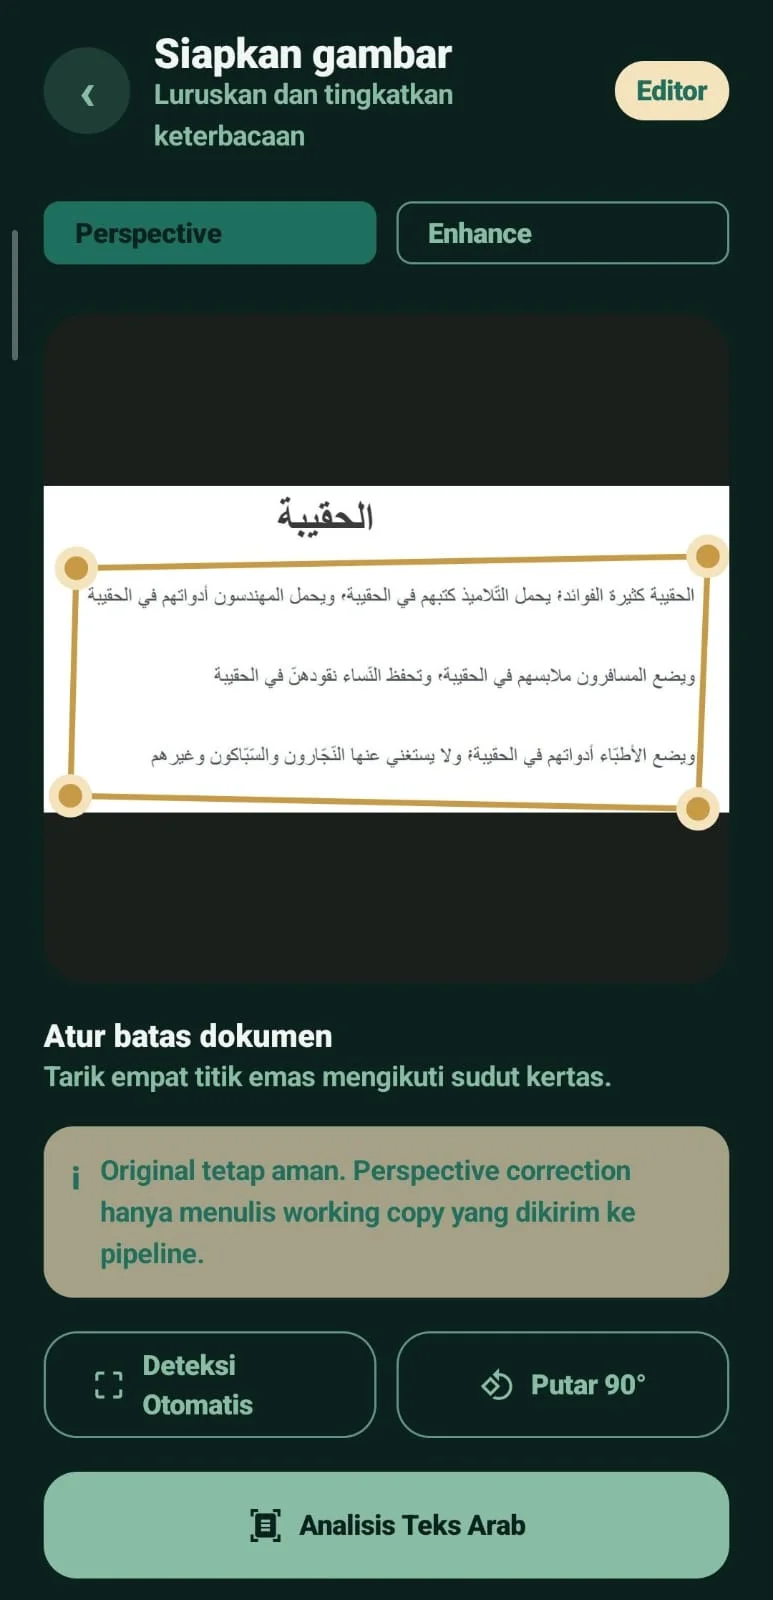
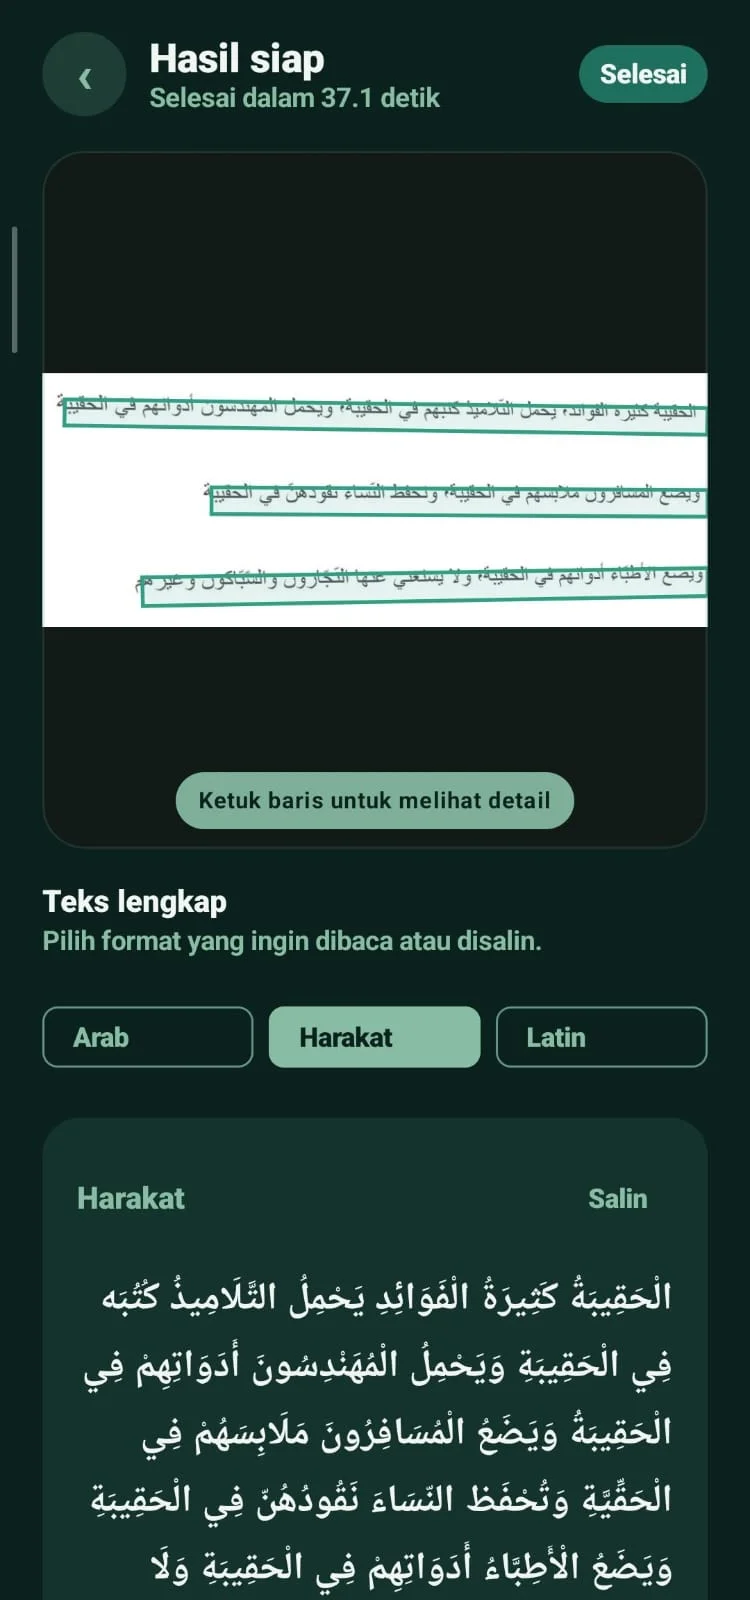
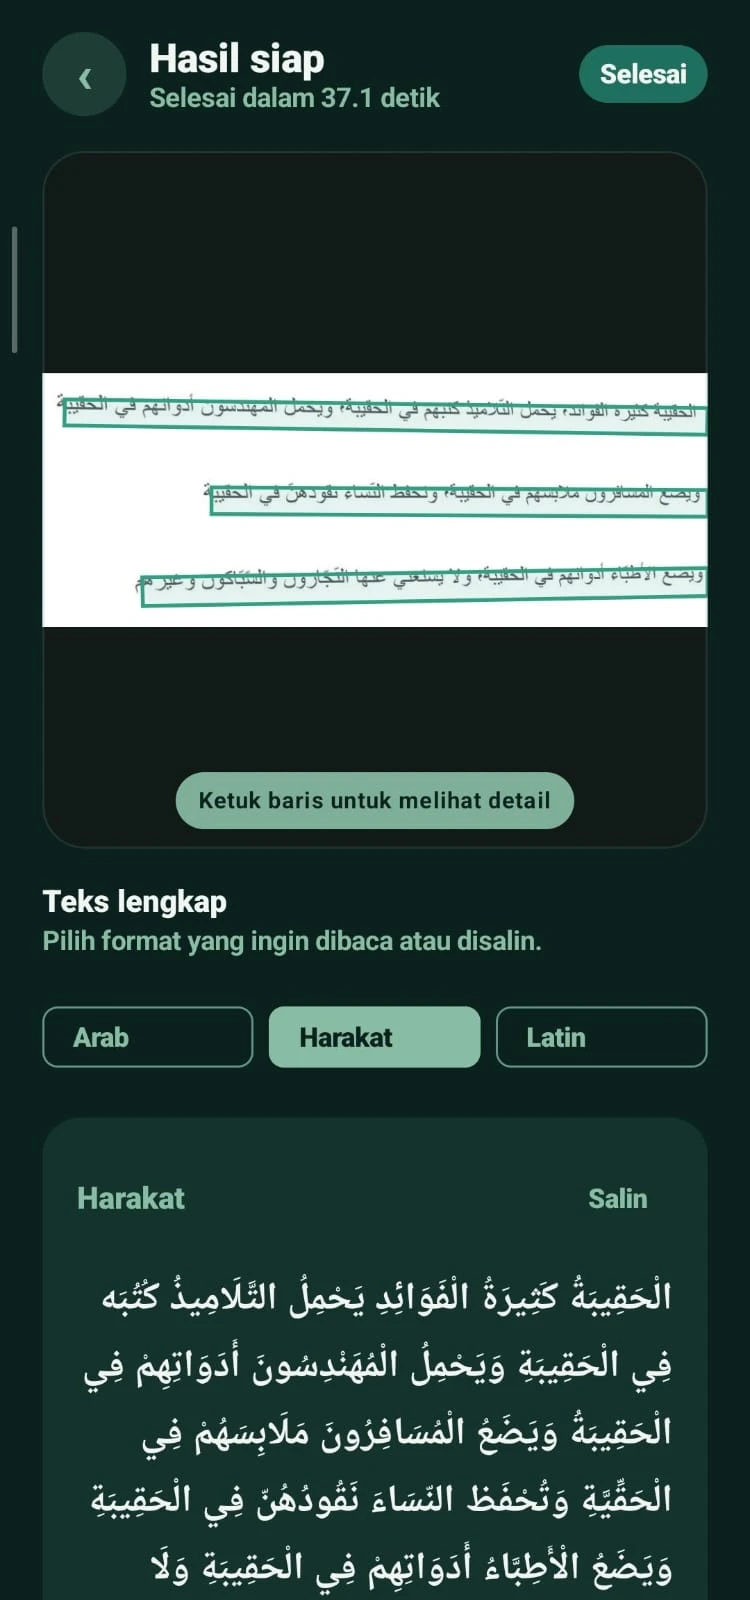
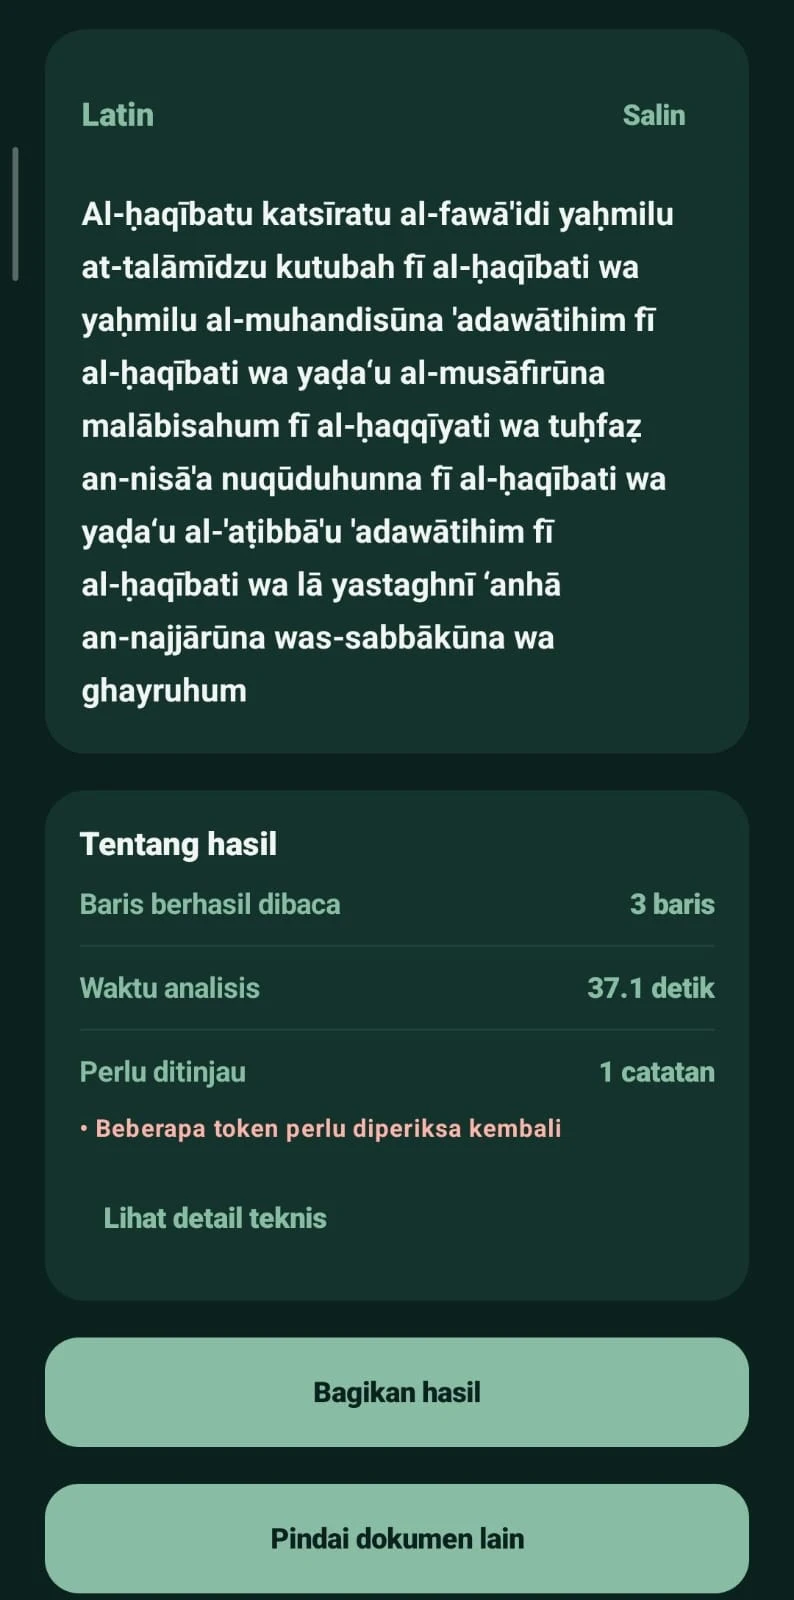
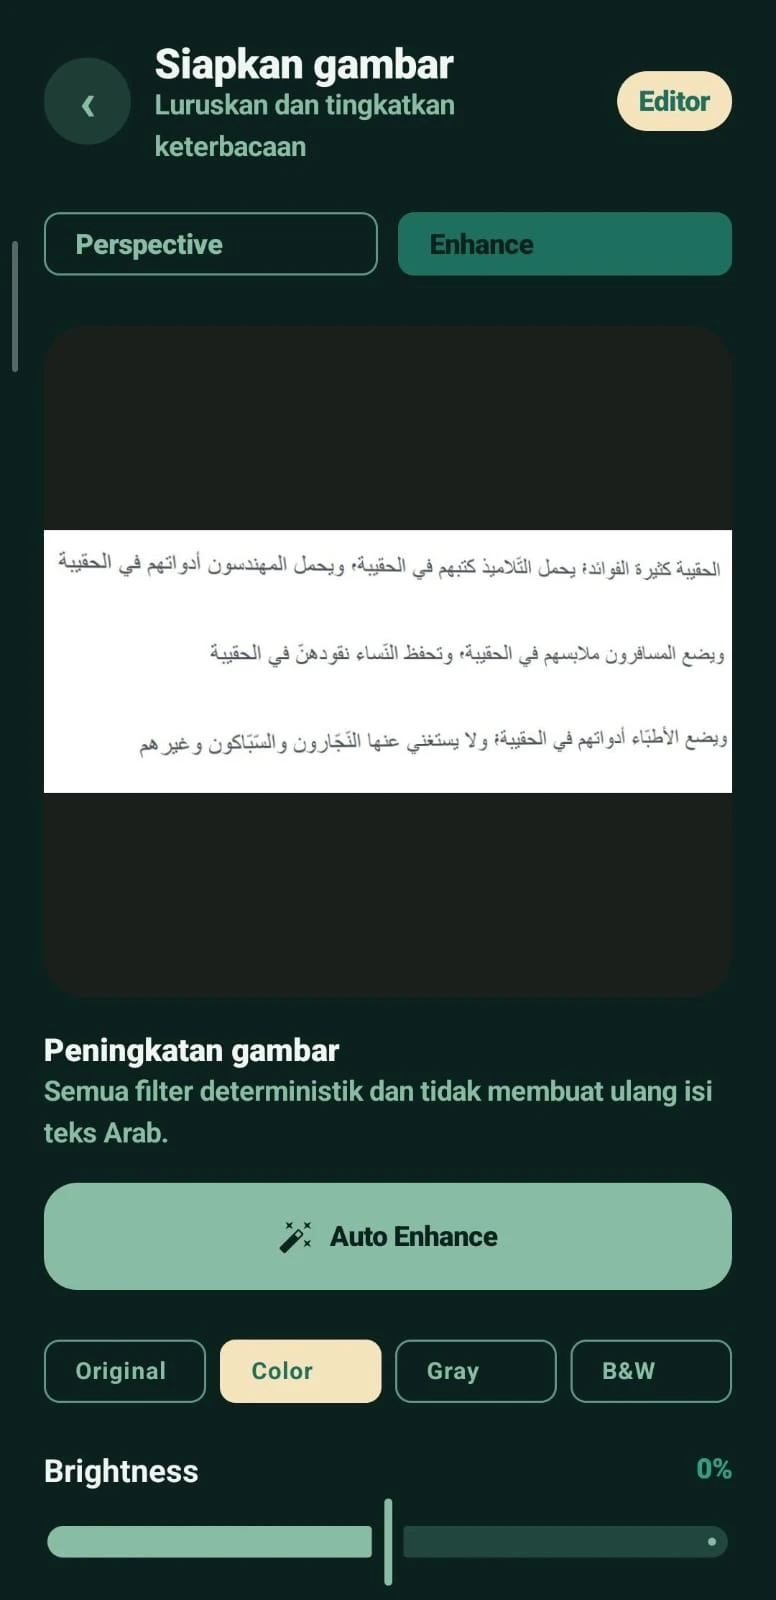
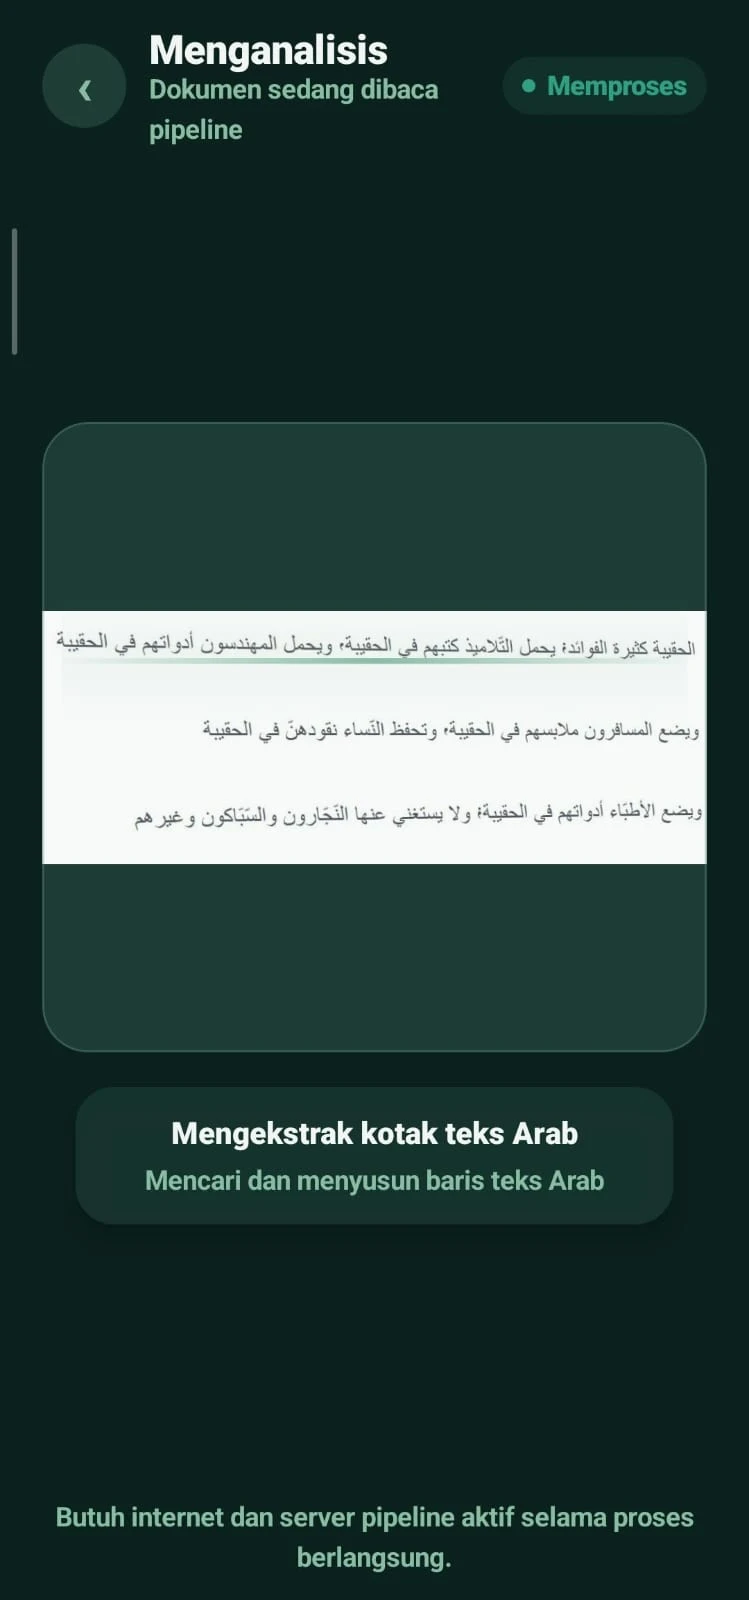
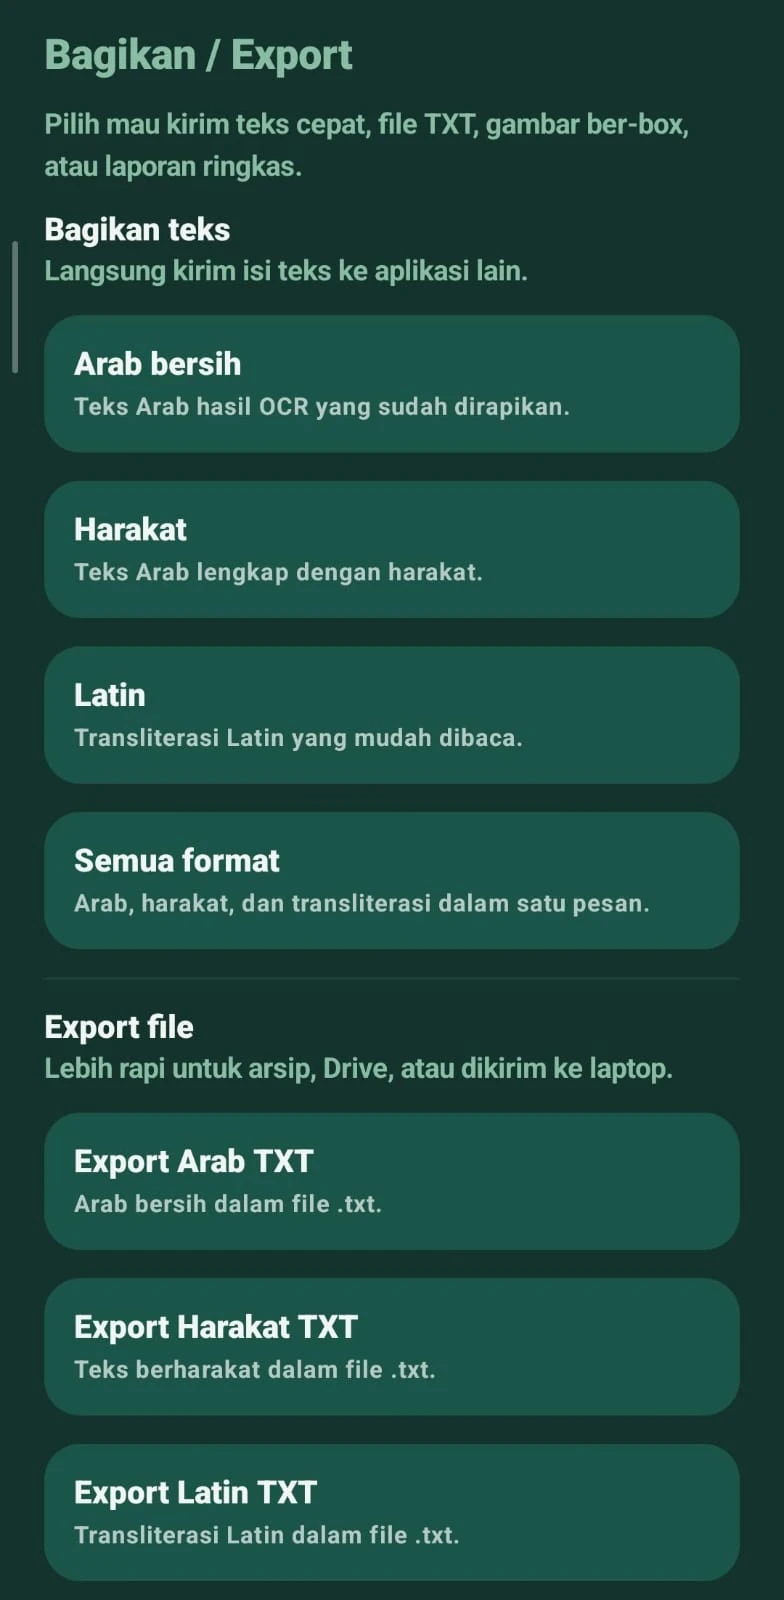
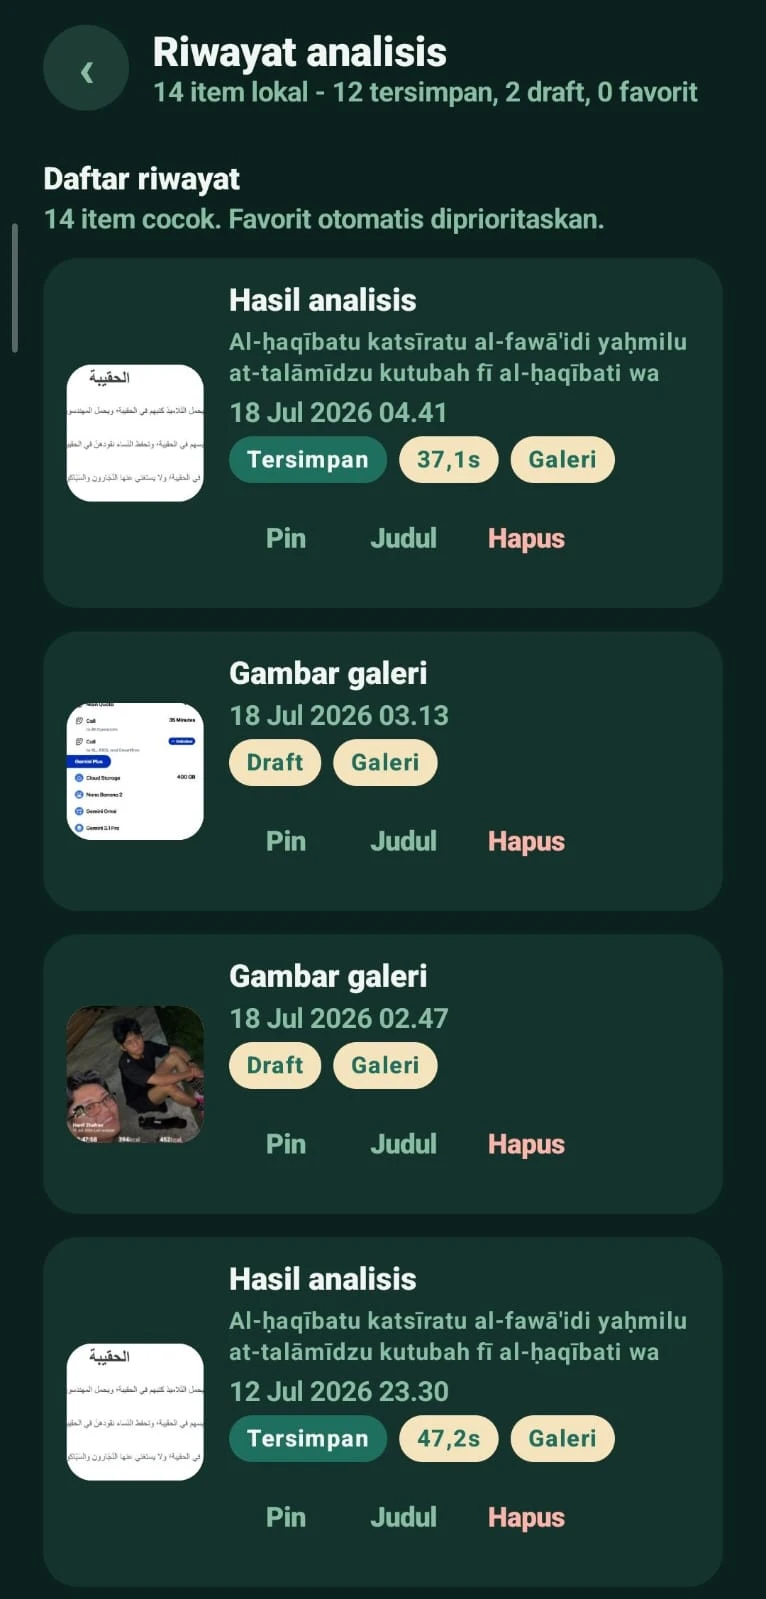
The Android experience includes capture, perspective correction, enhancement, progress, results, export, and saved scans. FastAPI exposes the pipeline.
What the evaluation shows
The original thesis evaluation reports mean character, word, and diacritic error rates across six samples. Lower values mean fewer errors in each stage.
- average CER
- 13.79%
character error rate
- average WER
- 23.15%
word error rate
- average DER
- 25.75%
diacritic error rate
A known limitation
Known limitation: classical handwritten Arabic remains difficult for this pipeline — character error rate rises to 40.52% on that subset. The results above are not a claim of flawless accuracy.
Inside the application
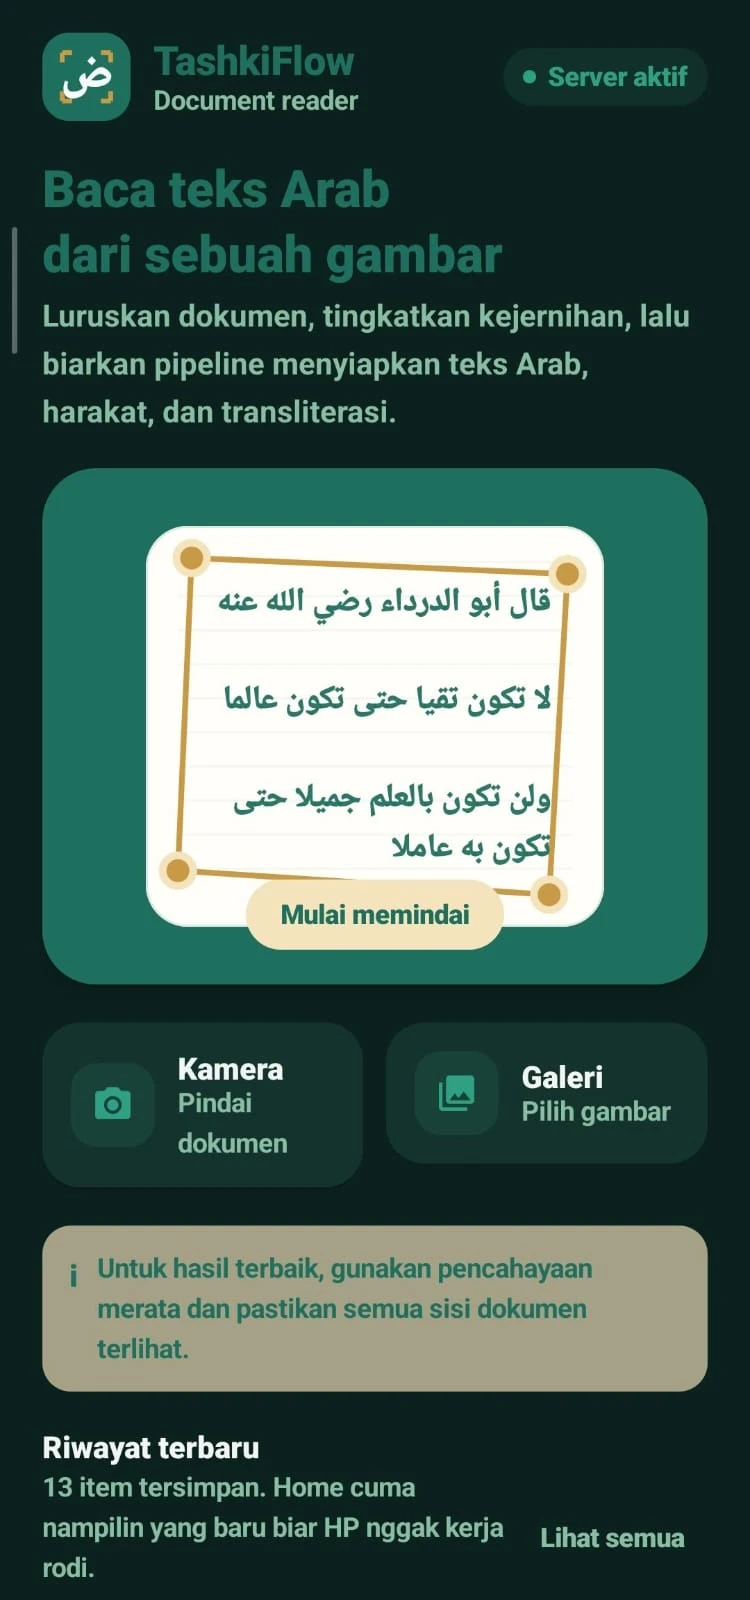
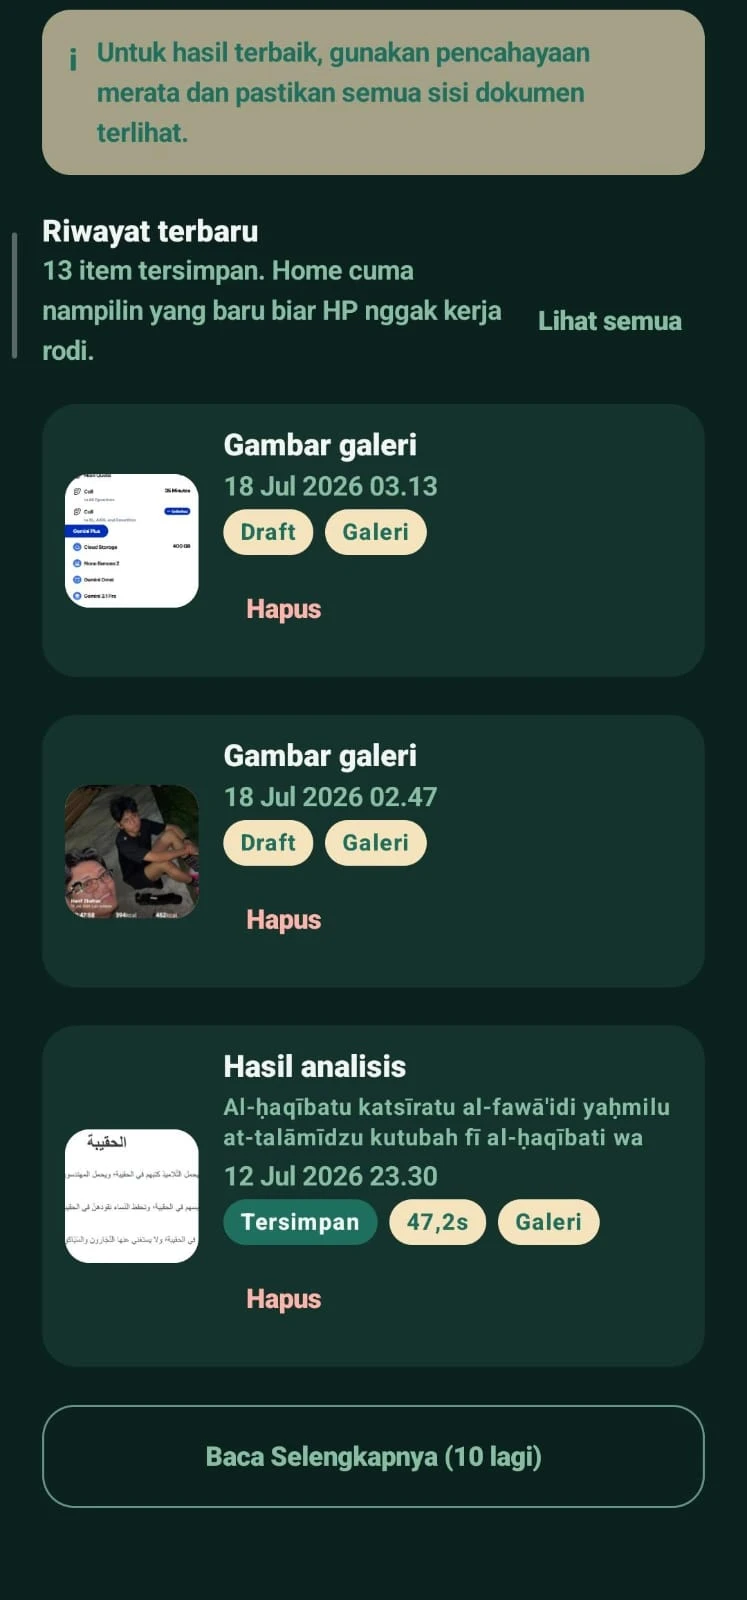
Original screenshots from the TashkiFlow experience. Open any image for a closer look.
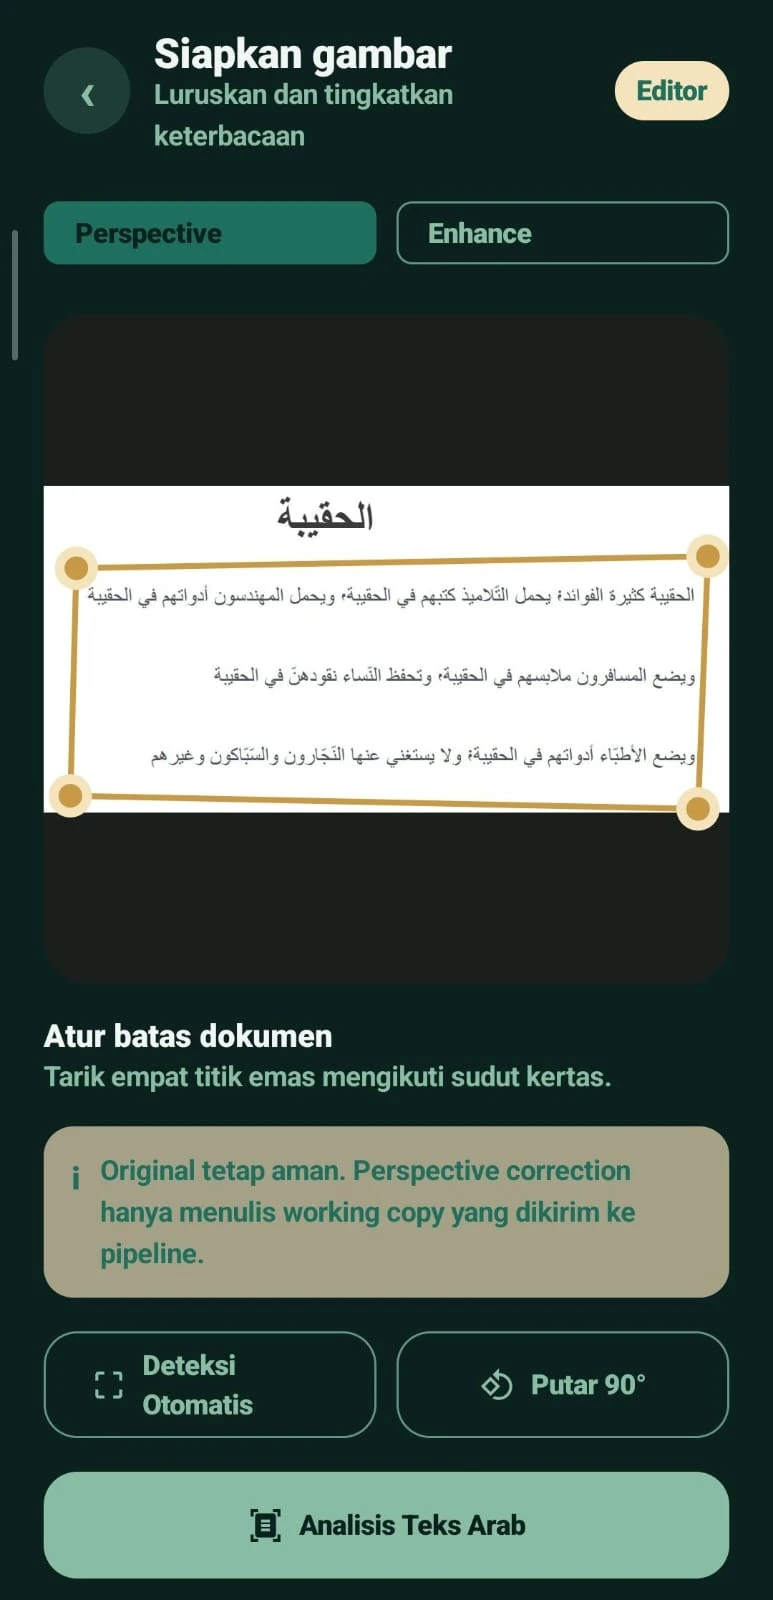
View the remaining 7 application screens
Evaluation evidence
The original figures and testing records behind the reported results.
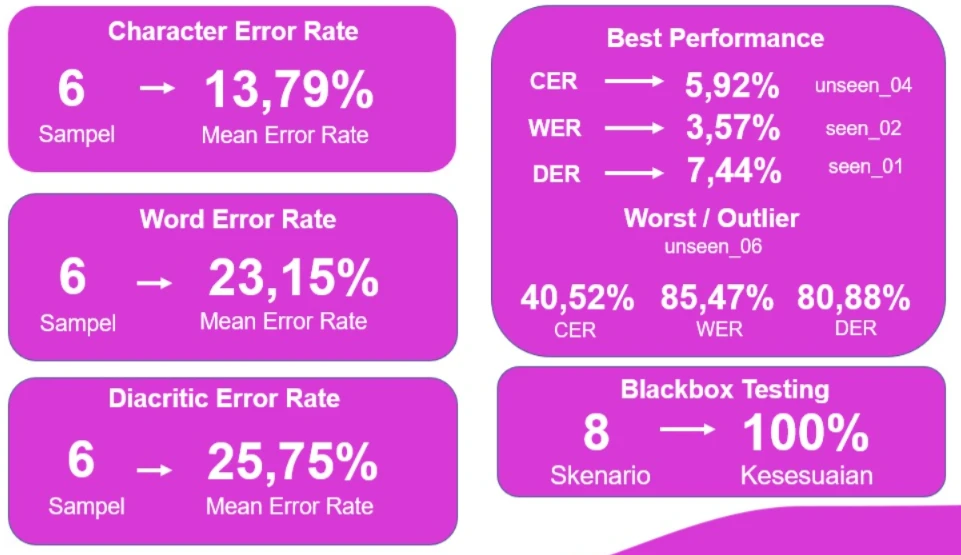
The original evaluation records mean character, word, and diacritic error rates across six samples, alongside eight black-box scenarios. The project also reports the worst sample separately.
How the pieces connect
A brief reading of the workflow, followed by the original implementation evidence.
- Capture & enhance
- Hybrid OCR
- Diacritize & transliterate
- Review & export
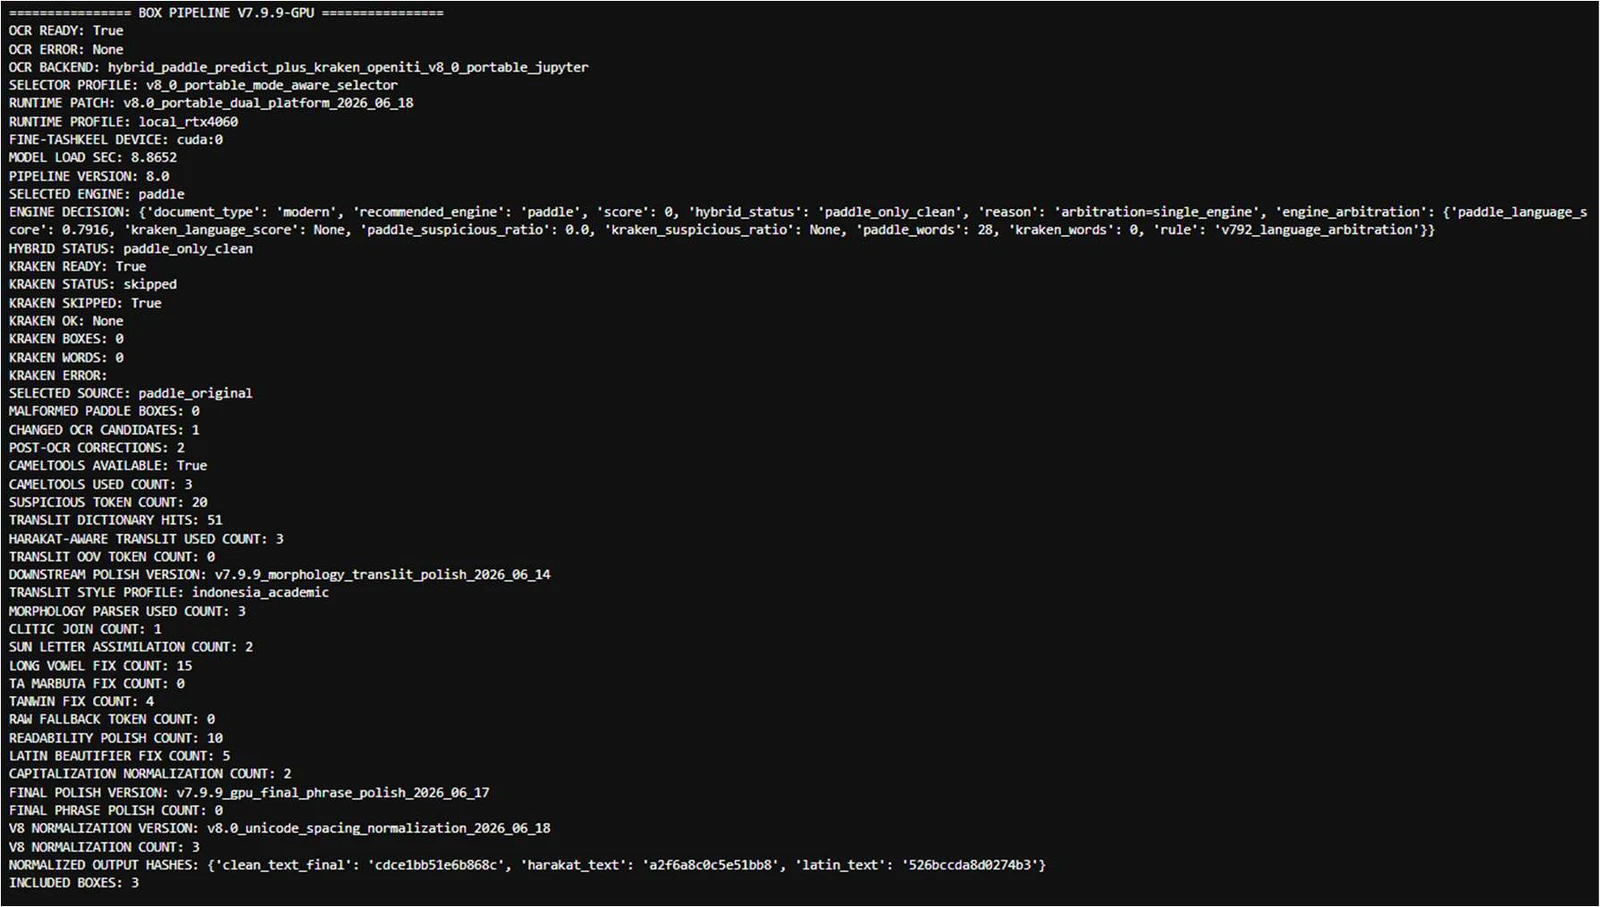
An original runtime record of the hybrid OCR arbitration stage.
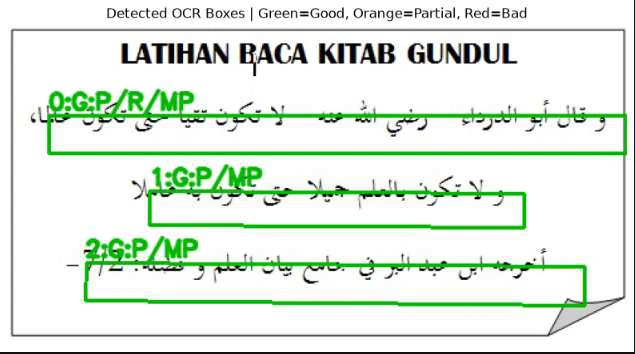
Recognition boxes over the scanned Arabic page.
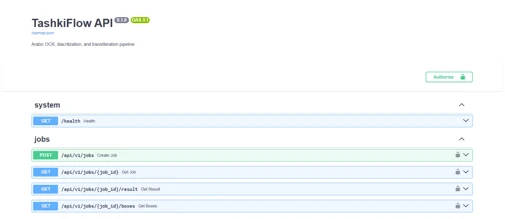
The original FastAPI documentation screenshot.